Separated H from K
Turned an implicit evaluation choice into the central controlled variable.
A planner can optimize a future it never executes. And a latent state can look close to the goal without offering a controllable route there. We isolated both interface failures and showed what changes when the evaluation matches the controller.
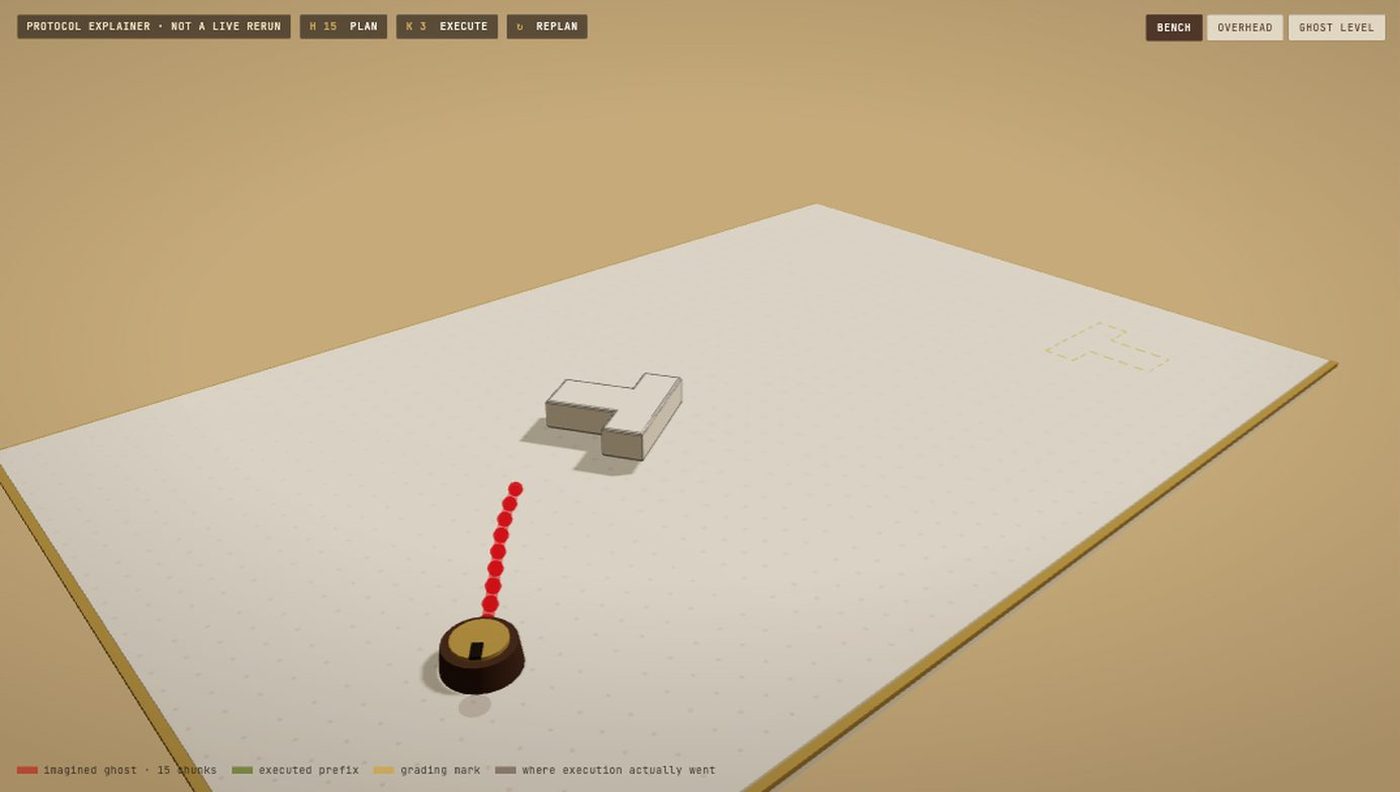
A staged world for both failure modes. Watch a fifteen-step plan grow and get thrown away three chunks at a time, then steer an agent through the detour that a scalar objective cannot see. Every number in its console is quoted from the paper. The motion is staged, not replayed.
Still image · click to load the world Open on its own page ↗
A world-model benchmark does not measure the model alone. It measures a chain: representation → objective → proposal mechanism → actuator. A mismatch anywhere in that interface can turn a usable model into an apparent failure.
Receding-horizon MPC plans to horizon H, executes only K action chunks, observes the new state, and replans. Terminal@H scores a state the controller will not directly reach before feedback changes the plan.
The objective rewards the imagined endpoint at H=15, although feedback arrives after K=3. The unexecuted suffix can dominate which prefix is selected.
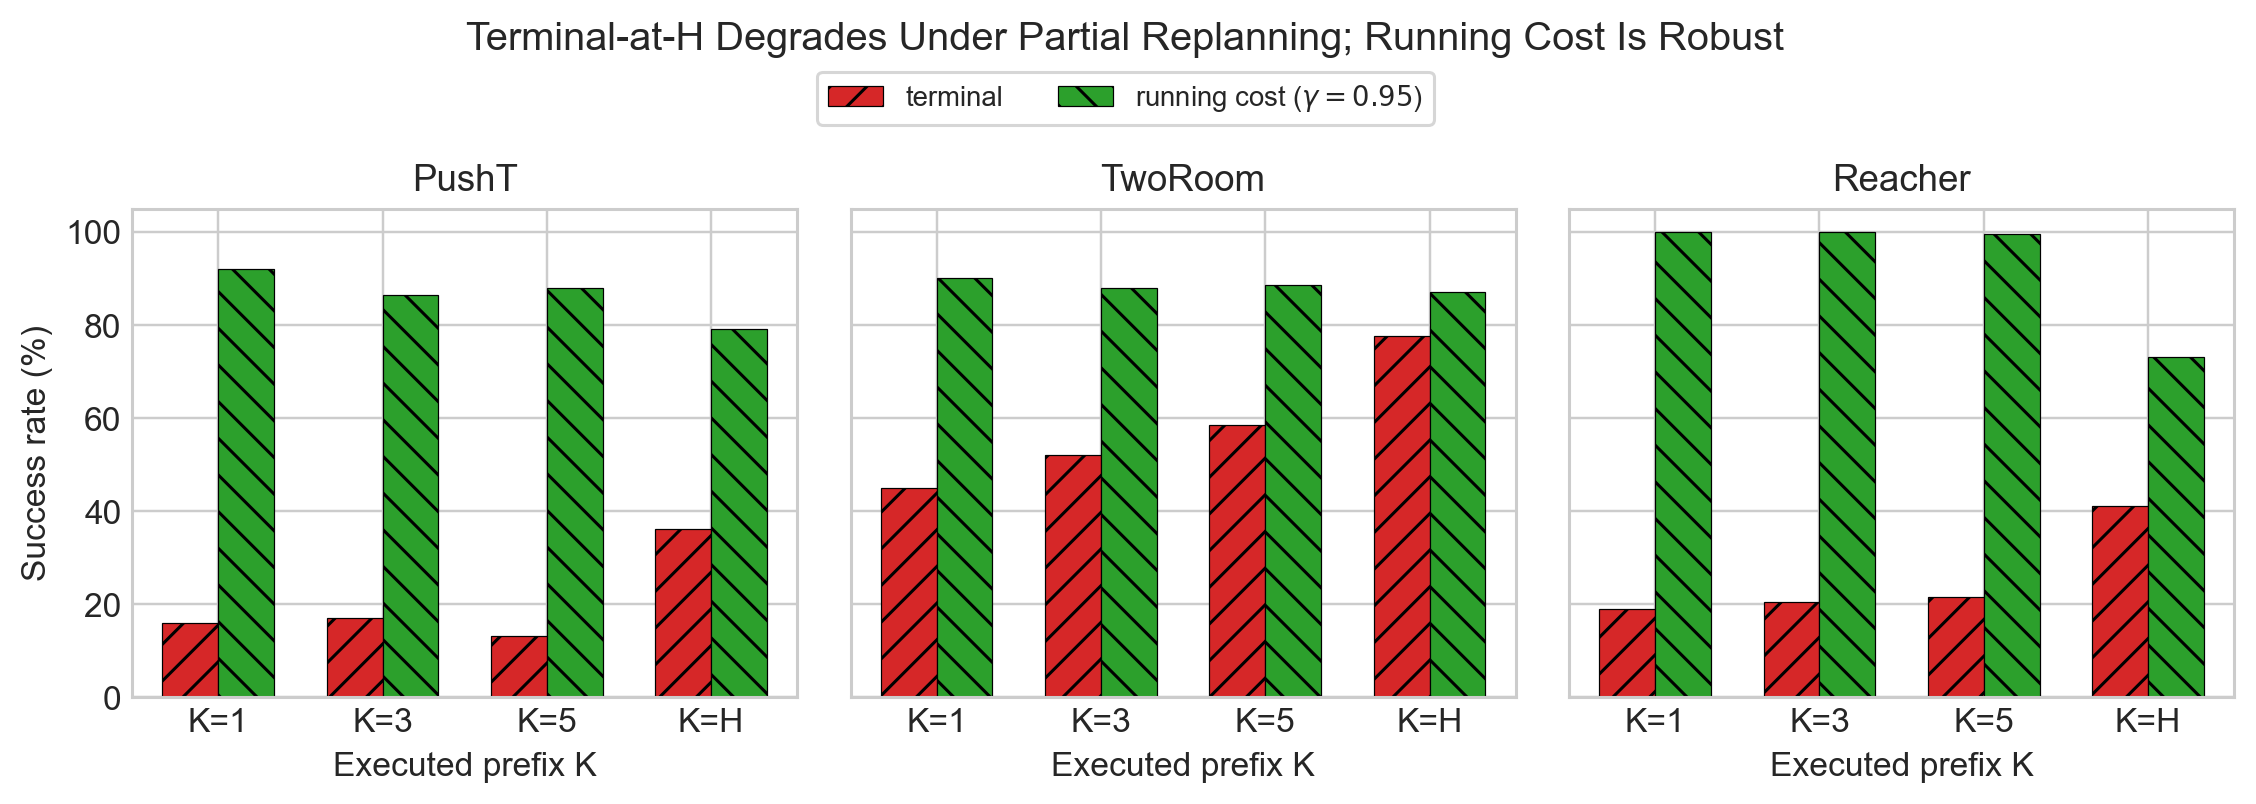
The same check changes TwoRoom from 52.0% to 83.5%; a running cost changes Reacher from 20.5% to 100%.
Across the measured replanning intervals K ∈ {1, 3, 5, 15}, terminal scoring is fragile under partial execution while running cost stays strong with frequent feedback. The intermediate PushT values are not monotonic. The finding is alignment, not a smooth performance law.
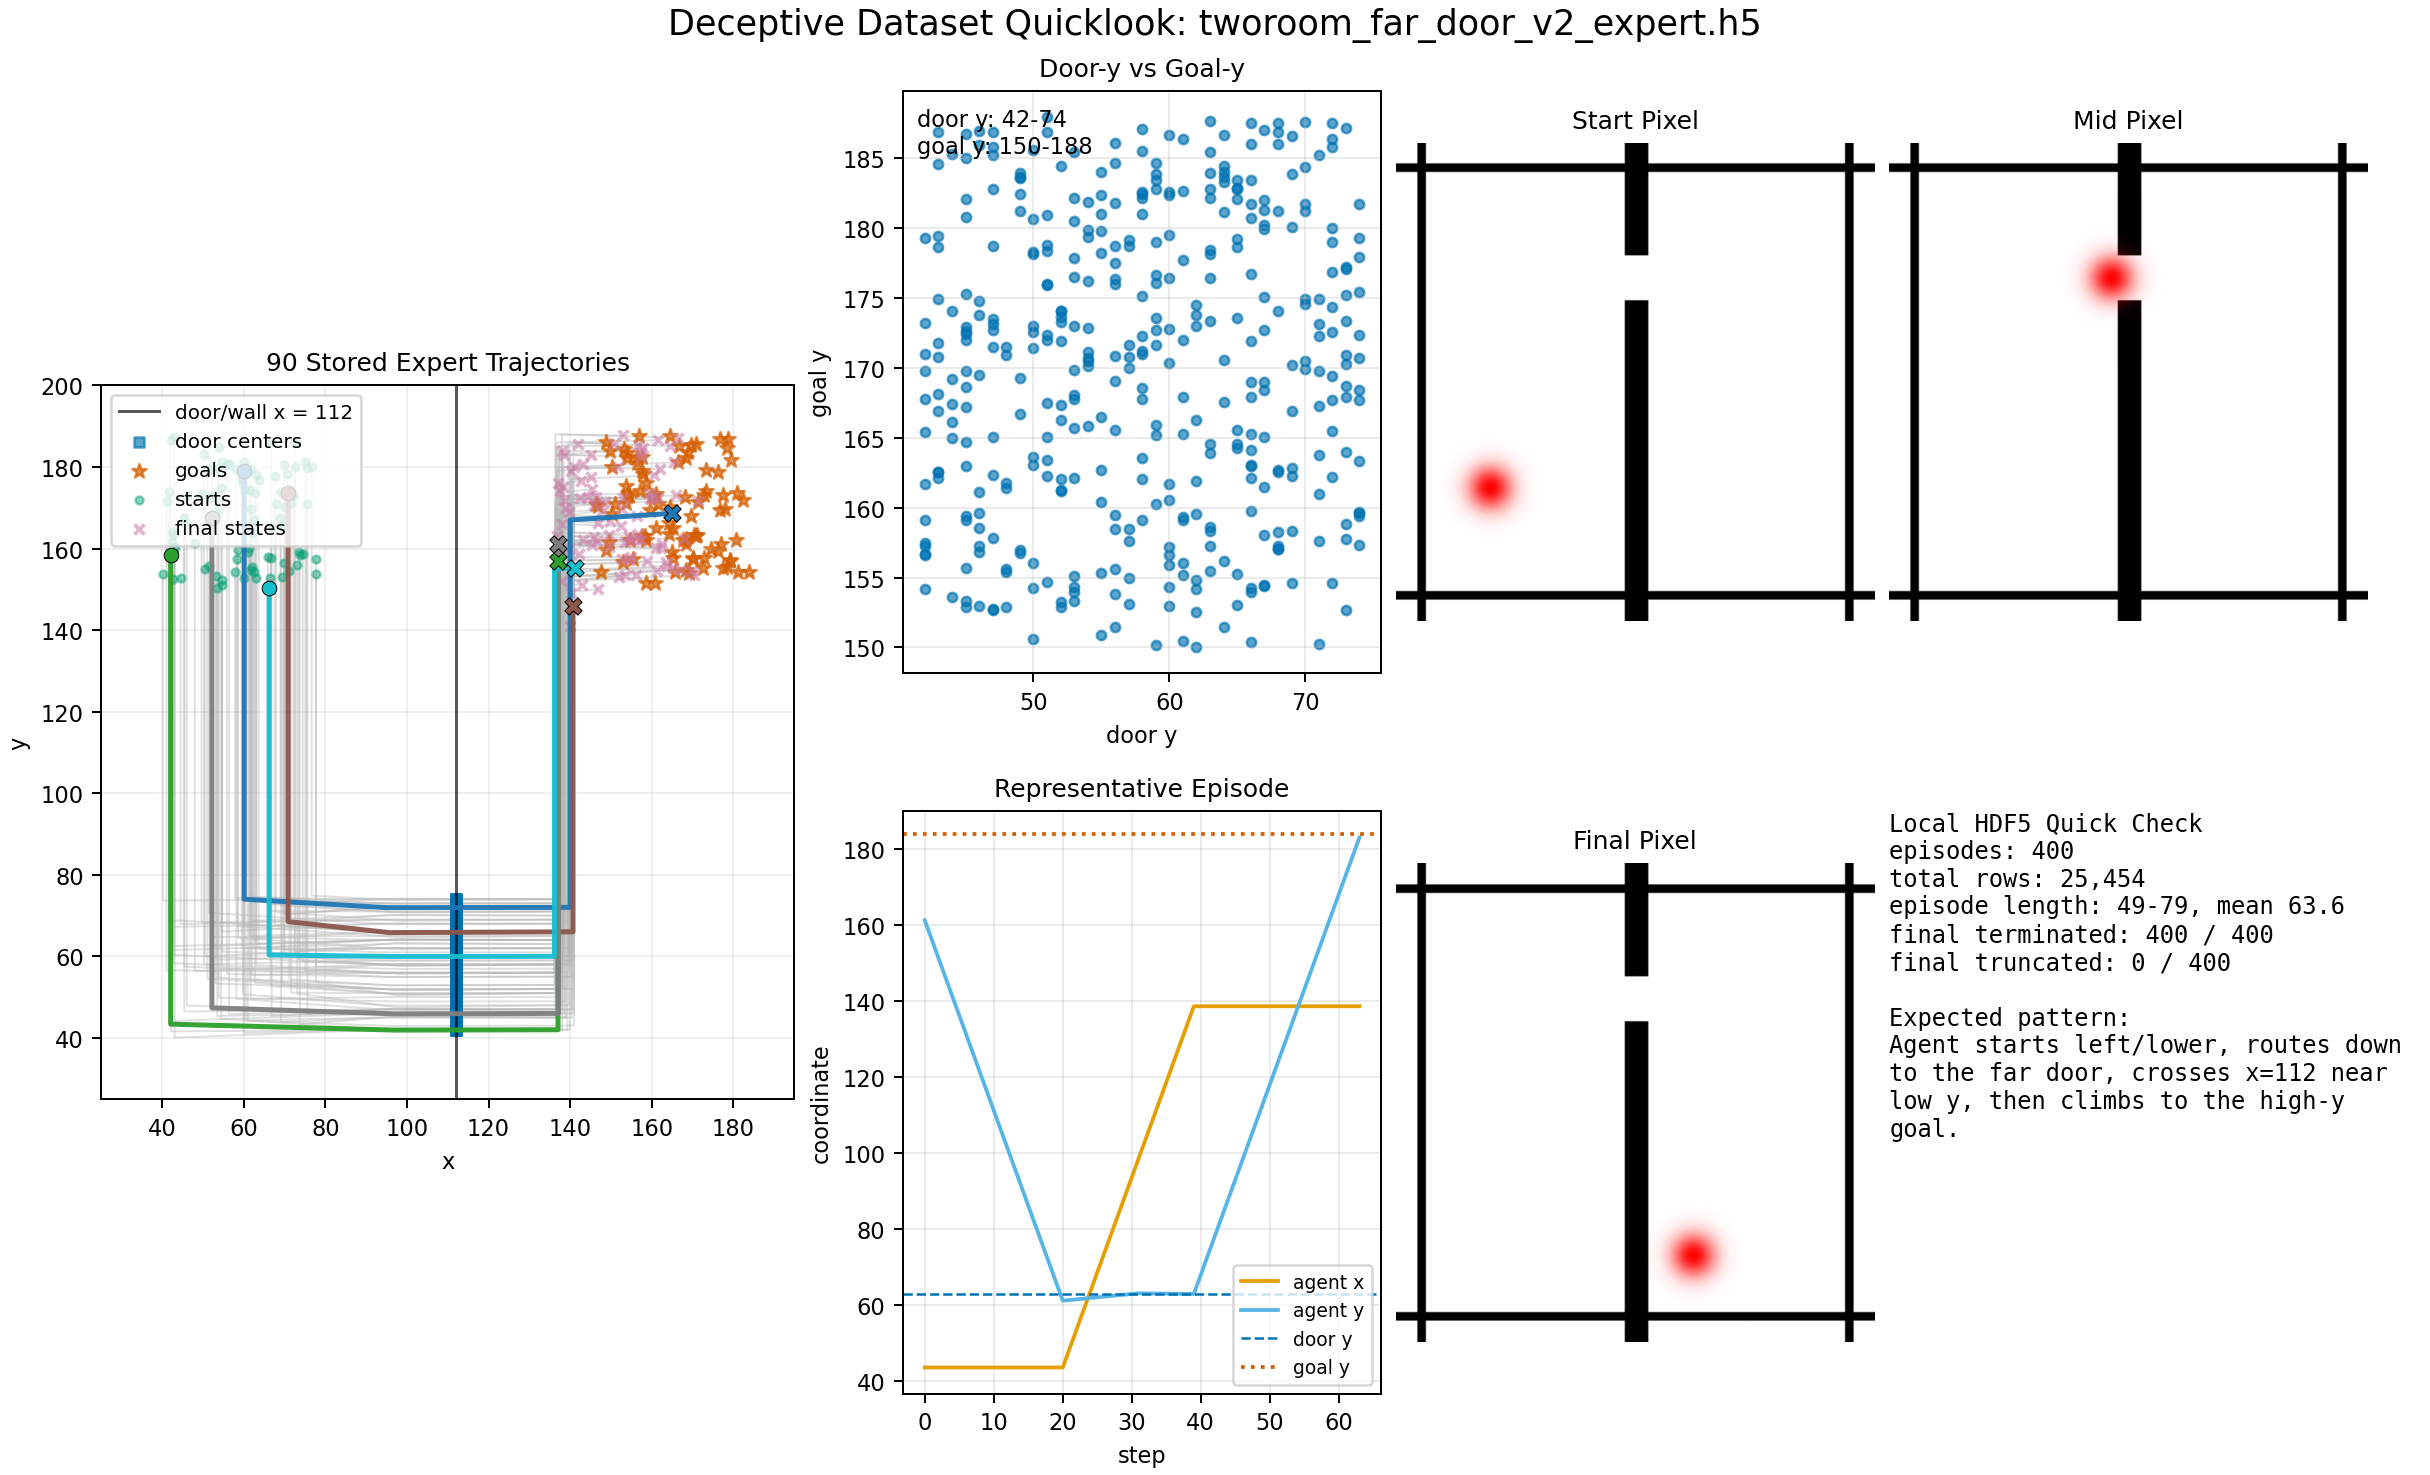
TwoRoom Far Door forces the agent to move away from the final goal to reach a distant doorway. Even aligned scalar objectives remain weak because they reward similarity, not locally executable progress through the bottleneck.
Matched-configuration reproduction on held-out fold 0. The agent starts left of the far doorway; the waypoint controller first redirects it through that opening. TwoRoom counts a hit when agent-goal distance is below 16; success is reach-once within the 75-step budget. The waypoint library and local actuator exclude that evaluation fold. The overlay is the solver's recorded selection, not an inferred path. The 92.7% headline is the paper's five-fold mean, not the outcome of this clip.
The stored expert trajectories descend to the low far doorway, cross the wall, then climb toward the high goal. The waypoint interface turns that detour into a sequence of locally executable edges.
Turned an implicit evaluation choice into the central controlled variable.
Compared terminal, prefix-terminal, running-cost, value, retrieval, and waypoint interfaces.
Created detour settings that distinguish latent similarity from controllable progress.
Reported strong retrieval controls and reset-state artifacts instead of hiding inconvenient evidence.